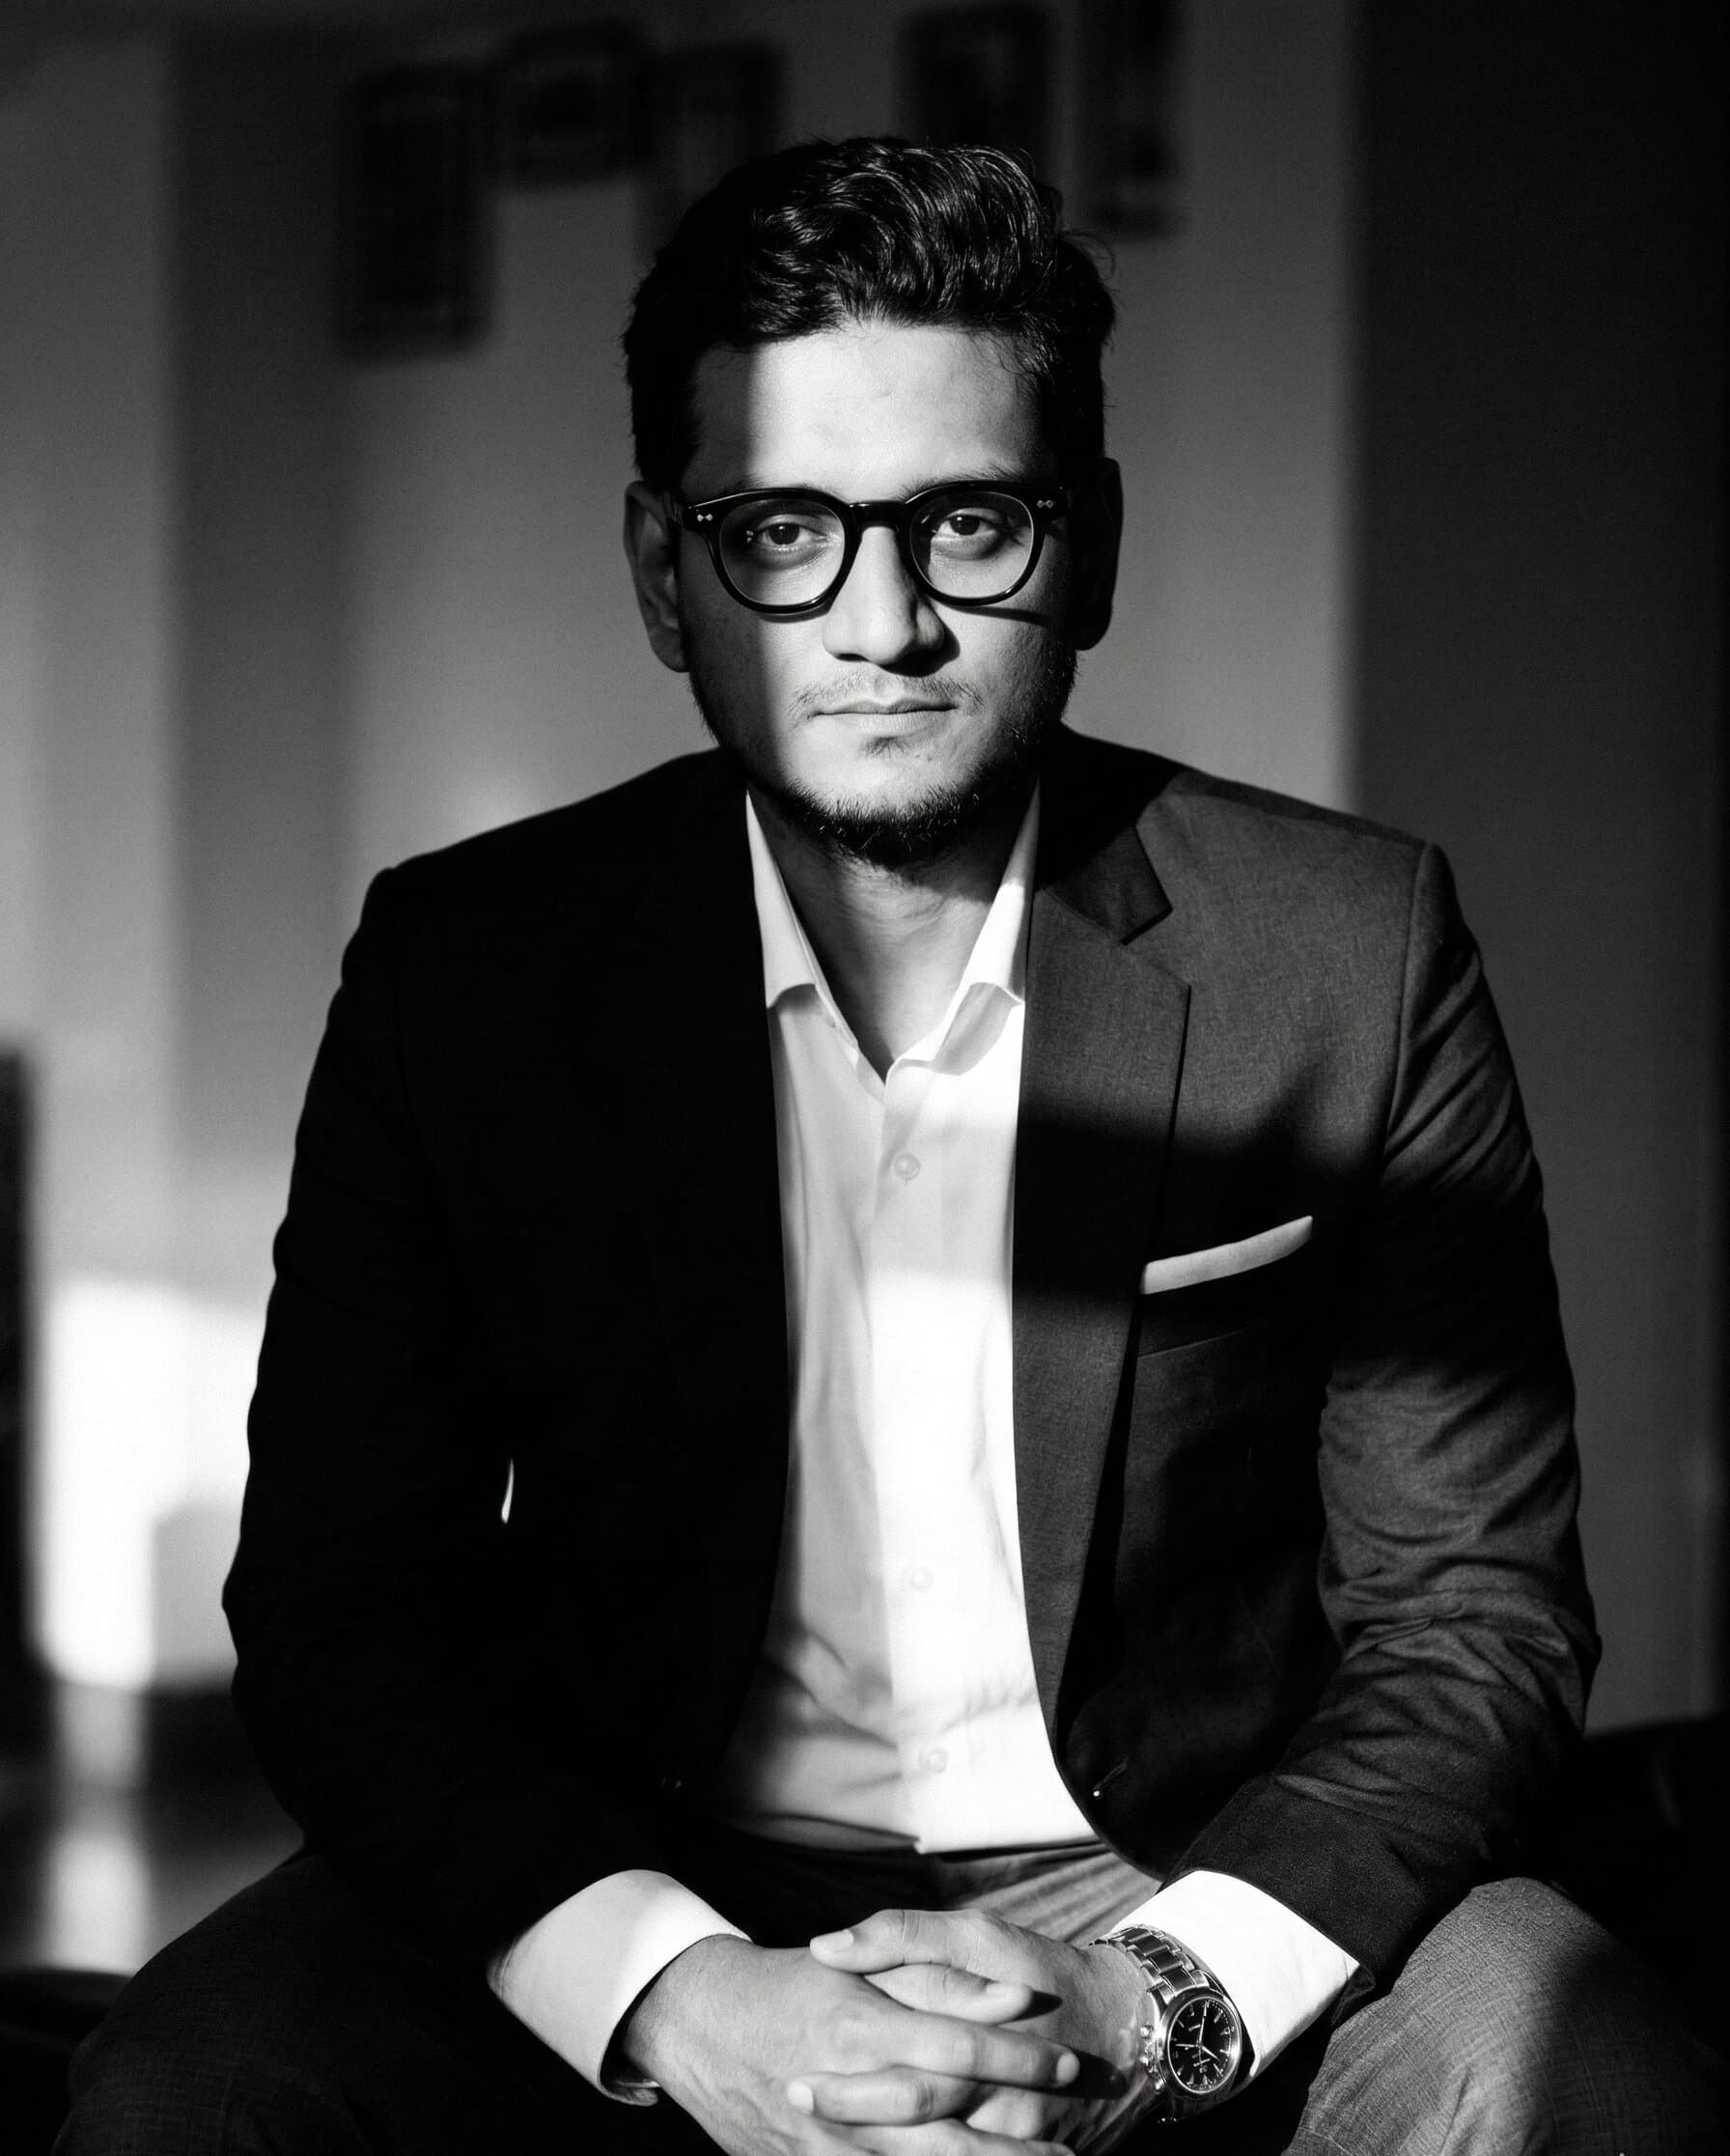
DATA SCIENTIST/AI ENGINEER
Data Scientist/AI Engineer with 4+ years of experience building and deploying intelligent solutions across machine learning, generative AI, natural language processing, and data science. Experienced in solving complex business problems through applied AI, automation, predictive modeling, and document intelligence, with a strong focus on turning research and experimentation into practical, scalable systems.
Articles & Technical Writings
Research articles, technical whitepapers, and production architecture specifications.
RLEF: Grounding Code LLMs in Execution Feedback with Reinforcement Learning
A detailed analysis of RLEF and how reinforcement learning teaches code LLMs to condition future generations on execution feedback rather than simply generating another independent answer.
KV Cache: Understanding Prefill, Decode, and Attention Caching
A technical walkthrough of KV caching, explaining how K and V are stored across decoder blocks, why Q is computed only for the current token, and how prefill and decode differ.
ML Data Is A First Class Citizen in Production
Why ML code in production is just a drop in the ocean compared to dynamic data pipelines, schema skew, and covariate drift.
Hierarchical Co-Attention for Visual Question Answering
Jointly reasoning about visual attention ("where to look") and question attention ("which words to listen to") across word, phrase, and question hierarchies.
Why Data Definition Is Hard in Real-World ML
The hidden trap of label inconsistency in unstructured datasets, resolving annotator disagreement, and establishing Human Level Performance baselines.
Why Low Average Error Isn't Good Enough
A 99.2% aggregate test accuracy can disguise complete failure on critical query cohorts, catastrophic edge cases, and high-value customer segments.
Automated Legal Document Intelligence: US Court Case Law PDFs to Compliant XML
Engineered a production-scale document intelligence pipeline for Thomson Reuters converting complex U.S. legal PDFs into structured XML/JAXML with zero content loss.
Multi-Dialect Text-to-SQL Pipeline with Vectorized Schema Caching & Pruning
Architected an enterprise Text-to-SQL system reducing generation latency by 75% via dynamic schema pruning, dialect-aware routing, and vector caching.
The Mathematics of Transformers: Attention, Projections & Softmax Geometry
A rigorous mathematical deconstruction of Scaled Dot-Product Attention, Query-Key-Value projection spaces, and temperature scaling proofs.
Curriculum Vitae & Experience
Data Scientist with effective over 4+ years of past experience specializing in Machine Learning, Deep Learning, and Natural Language Processing. Proficient in developing and deploying advanced analytical models to drive business insights and optimize processes.
ALGOLEAP TECHNOLOGIES
- Engineered a production-scale document intelligence pipeline for converting complex U.S. legal PDFs into structured XML/JAXML outputs using Claude Sonnet-based LLM workflows, achieving zero content loss and reducing processing time from 3 hours to under 5 minutes for 20-document batches.
- Developed a document intelligence pipeline for extracting and mapping footnotes to in-text references from complex PDF documents using GPT-5.2, Python, and LLM-based extraction workflows.
- Developed an AI-powered document transformation pipeline that processes tracked changes in Word documents, applies rule and LLM-driven content modifications.
PRATHAM SOFTWARE
- AI Ticket Automation for Logistics: Architected an AI-driven ticketing workflow using LangGraph, FastAPI, and Azure OpenAI to automate complex task categorization, summarization, and resolution. Engineered Retrieval-Augmented Generation (RAG) pipelines with Pinecone for vector search, structuring the agent routing, tool-calling, and fallback handling to successfully auto-resolve 90% of tickets and reduce manual operational effort by 80%.
- LLM Text-to-SQL Pipeline: Led development using LangChain and OpenAI to translate natural language into complex SQL for multi-dialect engines. Designed semantic layers and integrated Pinecone for accurate schema retrieval, optimizing query latency by 75%.
- AI Agent for NDA Conflict Resolution: Developed an agent with GPT-4 and Azure ML Studio to analyze NDAs and flag conflicts; integrated with Microsoft Teams for seamless contract review within enterprise workflows.
LANDMARK GROUP
- Analyzed business requirements and provided data-driven solutions for stakeholders across various MARKETPLACE.
- O2O Propensity Model (GCC Region): Developed a model achieving a 50% improvement over traditional methods, effectively targeting 90% of customers in the top 3 deciles, with an event rate of 1.5% or less across 6 countries.
- Acquisition Model (Homecentre UAE): Targeted the top 5% of customers, achieving 80% coverage and a lift of over 2 in top deciles.
- MLOps Pipeline (Centrepoint UAE): Designed and deployed a Stage 1 pipeline to generate customer propensity scores, enabling efficient forecasting for targeted campaigns.
EUNIMART PVT LTD
- AI Service for SEO: Built a service for keyword and volume prediction to optimize omnichannel e-commerce platforms.
- Personalized Onboarding Journey: Developed a user onboarding system with 95% statistical significance, improving user flow and reducing friction points.
- Image Blur Removal: Enhanced and deployed an image deblurring solution for e-commerce platforms, reducing model size by 40%.
iNEURON INTELLIGENCE
- Developed a Computer Vision solution for visually impaired individuals, employing Multimodal learning (CV+NLP) for "Visual Question Answering."
- Implemented the Hierarchical Co-attention paper, enhancing the model capabilities and contributing to advancements in attention mechanisms.
EXPOSYS DATA LABS
- Implemented clustering algorithms on mall data to identify customer segments, optimizing targeted marketing strategies.
THE SMARTBRIDGE
- Implemented a Random Forest model for "Quality Prediction in the Mining Process."
- Applied machine learning techniques to analyze and predict the quality of mining outputs, contributing to process optimization.
Initiate Contact
Available for Applied Machine Learning, MLOps, LLM Systems & Research Engineering discussions.